

The CXL Consortium is returning to Supercomputing 2026 (SC26) to showcase the benefits of CXL for AI and HPC applications.
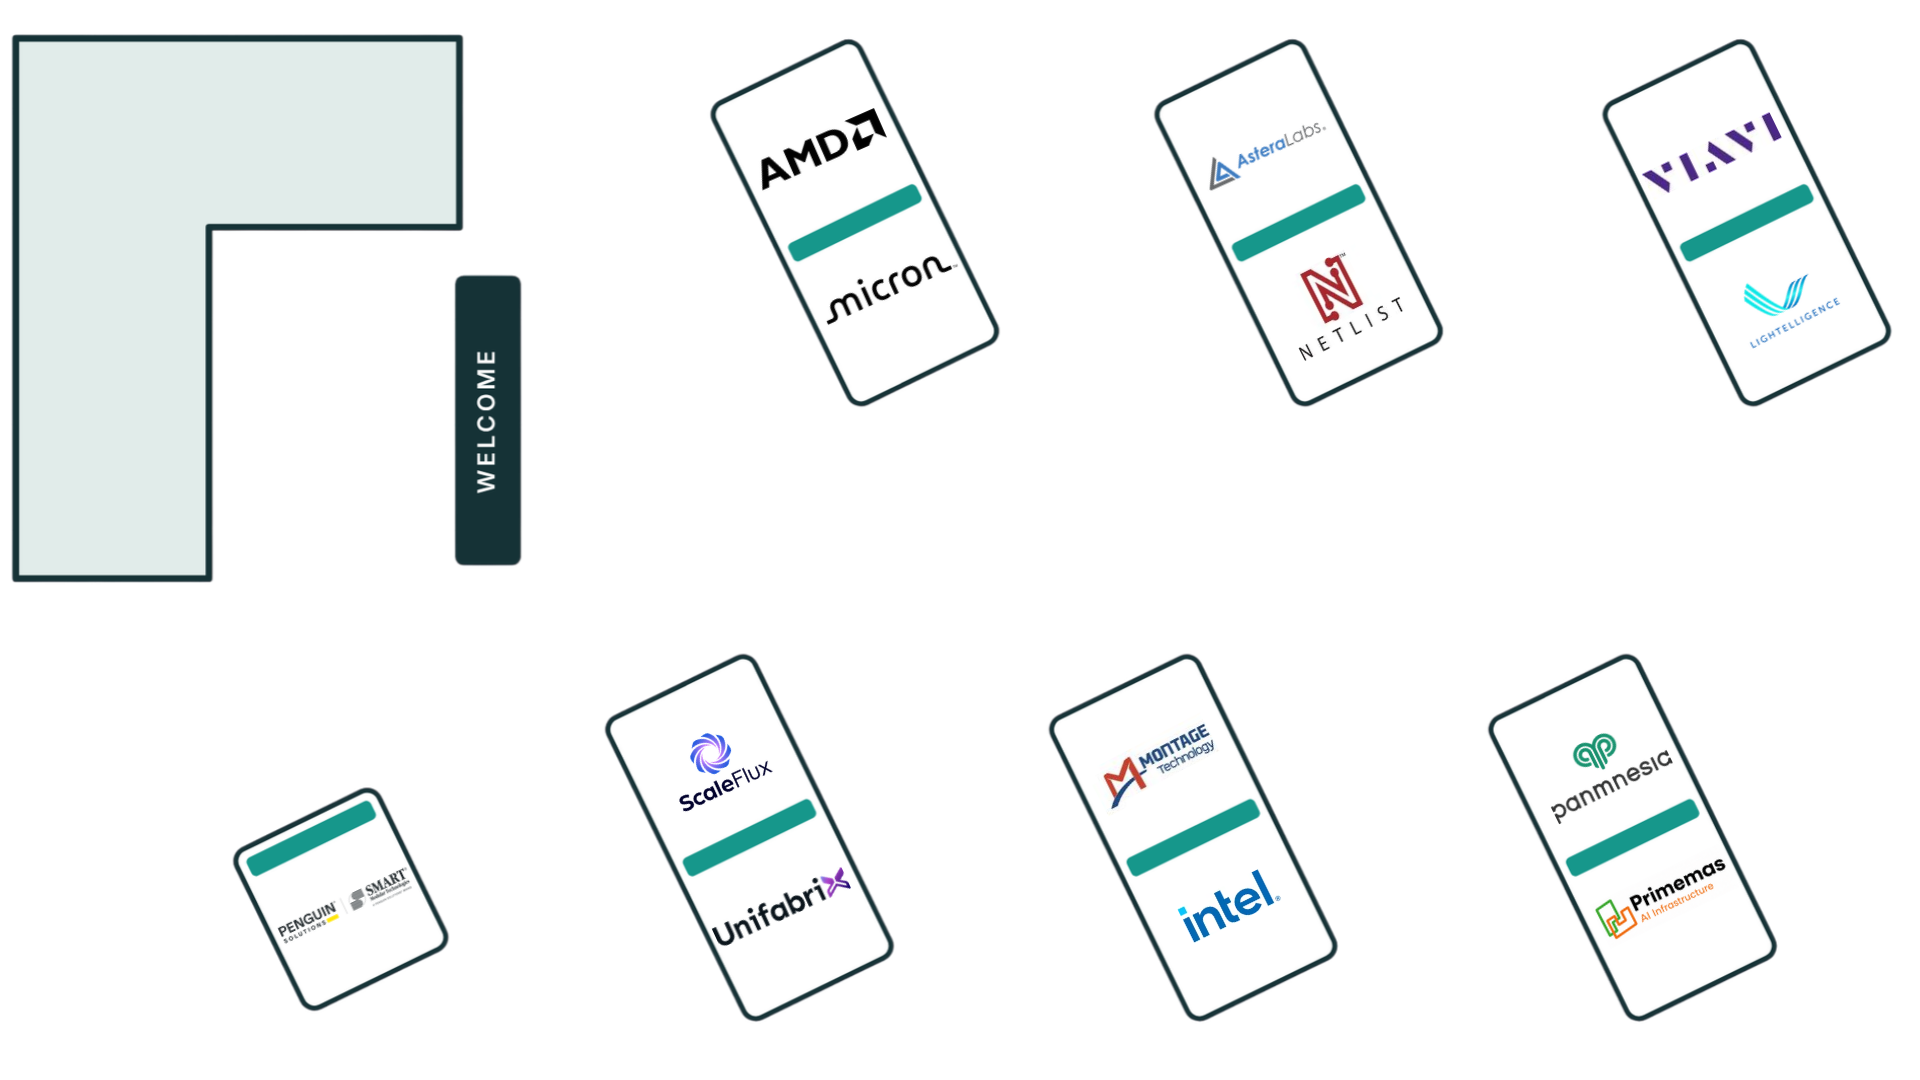
CXL Pavilion (Booth no. 1218)
Visit the CXL Pavilion to view the following CXL demonstrations:
AMD | Powering Next-Generation Agentic AI with AMD Epyc and CXL Gen6 Expanded Memory
Astera Labs | From Bottleneck to Breakthrough: Accelerating AI Inferencing for Agentic AI with Leo Smart Memory Controllers
Intel | Optimize Memory TCO with Intel® Flat Memory Mode for Agentic AI on Future-Gen Xeon Processor
This demo features a next generation Intel Xeon CPU with Flat Memory Mode that enables higher-density AI agent sandbox deployments in systems with CXL attached memory. We demonstrate an increase in sandbox capacity while maintaining near-DRAM performance, with just a 2% increase in p99 latency. In contrast, software-based memory tiering introduces higher latency for the additional sandboxes. By transparently leveraging CXL memory capacity, Flat Memory Mode enables more AI agents per server while maintaining DRAM class performance.
Lightelligence | CXL 3.X Over Optics
Lightelligence will demonstrate the benefits of CXL-based memory expansion to improve workload efficiency using the Photowave™ Active Optical Cables.
Micron | Abaco Reference Design: Redefining DRAM as Shared Infrastructure for Scalable Agentic AI
We will present the use of a CXL-based pooled memory system, as part of the Abaco System reference design and show its ability to enable from 10X to 30X performance of Agentic AI workloads by providing access of the shared memory pool to servers/GPUs within the rack. We will also highlight and explain the use of the famfs Linux kernel addition to seamless enable software applications, like in Dynamo, to leverage the memory pool.
Montage Technology | CXL Dynamic Capacity Device (DCD) Technology
The demo showcases:
• Multi-host CXL memory sharing using Montage MXC Gen3 silicon
• Dynamic memory allocation between multiple active servers
• Real-time memory expansion and release without physical hardware changes
• Practical implementation of CXL Dynamic Capacity Device (DCD) technology in a working system
Netlist | Unlocking the Full Potential of CXL Memory Solutions for AI, Cloud, and Enterprise
Netlist will showcase three CXL memory proof-of-concept designs: NVvaultTM-HM, which uses DRAM as a high-speed cache for NAND-backed capacity to tier hot, warm, and cold data; NVvaultTM-PM, a CXL Type 3 device that pairs low-latency DRAM with onboard NAND backup and an embedded energy source to keep data safe through power loss; and NVvaultTM-D4, which turns existing DDR4 modules into expanded host memory. These designs target AI infrastructure, KV-cache management, AI/ML checkpointing, in-memory databases, virtual machines, HPC, and other memory-intensive workloads. Together, they show how CXL can support intelligent memory tiering, persistent memory, and DDR4 reuse to improve capacity, performance, data persistence, and memory efficiency.
Panmnesia | CXL 3.2 Fabric Switch Supporting Port-Based Routing
At this exhibition, Panmnesia will present its CXL 3.2-PCIe 6.4 Fusion Switch silicon, equipped with its proprietary low-latency CXL controller, together with the accompanying development kit. Building on this technology, Panmnesia will showcase demonstrations in which CXL capabilities—including port-based routing and memory sharing—are applied to real workloads such as database processing, HPC, and AI, showing how they improve resource utilization and end-to-end application performance.
By exercising these CXL features on workloads that SC attendees encounter in production, we expect this demonstration to illuminate the practical value of CXL and to encourage broader adoption of CXL-based system designs.
Penguin Solutions | DDR4 Reimagined: Expanding DDR5 Server Memory with CXL
Maximizing Legacy Assets: Penguin’s SMART CXL DDR4 AIC Expansion Demo
Upgrading to DDR5 doesn’t mean your DDR4 investments have to end up in a landfill. In this demo, we showcase Penguin’s innovative 8-DIMM CXL AIC, designed to breathe new life into decommissioned memory.
Primemas | Expand Memory Beyond Limits
See how CXL memory capacity speeds up LLM inference. We run the same workload on the same GPU with 2 TB and 4 TB of CXL memory for the KV cache.
With 4 TB, the entire cache fits, which delivers 2.9× higher throughput and 3.3× faster time-to-first-token, without adding GPUs.
ScaleFlux | MC600 CXL Memory Expansion
The ScaleFlux MC600, a CXL 3.2 Type 3 memory controller, adds 512GB of DDR5 to a host server over PCIe Gen6, expanding memory capacity for AI and cloud workloads. Its RS ECC corrects 11 symbol errors across any two DDR5 chips, delivering industry-leading RAS at about 6.5W typical power.
UnifabriX | POOL IT. SHARE IT. ACCELERATE AI. Powered by UnifabriX MPU
The PoC showcases a disaggregated memory architecture built on CXL Dynamic Capacity Devices (DCD), where memory is no longer statically attached to a server but exposed as a shared, fabric-level resource. Through a programmable API layer, the system enables real-time allocation and deallocation of memory capacity across multiple hosts, without reboot, reconfiguration, or application interruption.
VIAVI | CXL® 3.X Link-Up Through Unretimed LPO
A complete CXL 3.X linkup with protocol-prescribed negotiation between VIAVI’s 6P16 and Qualcomm Dragonally’s CXL EVB, established over optical link.
Exhibitor Forum Presentation: Building the Future of AI Infrastructure With CXL
- Date and time: Tuesday, November 17, 2026, from 1:30 – 2:00 pm CT
- Speaker: Anil Godbole, CXL Consortium Marketing Working Group (MWG) Chair
- Description: Discover how the Compute Express Link® (CXL®) ecosystem is helping solve the memory challenges limiting today’s AI infrastructure. Recently, leading cloud service providers and GPU manufacturers have highlighted CXL memory pooling as an effective approach for improving KV cache access and enabling more efficient AI inference at scale. This Exhibitor Forum session highlights the growing momentum behind CXL adoption, featuring demonstrations from CXL Consortium members that showcase memory expansion, pooling, composable infrastructure, software enablement, validation, and production-ready solutions. Attendees will gain insight into how a diverse ecosystem of silicon providers, system manufacturers, software developers, and infrastructure companies is working together to bring CXL to market and address the memory and infrastructure challenges of modern AI workloads.
Follow the CXL Consortium via LinkedIn for updates!